Woven runs engineering scenarios, such as a code review or a production bug, scored by two certified engineers, and lets candidates bring their own AI model. Lemonsignal gives a real task to roles beyond engineering, records the whole conversation with the AI, and gives your team a first read to check.
Woven vs Lemonsignal: side-by-side comparison
What Woven says on its own site, checked 28 Oct 2026, next to Lemonsignal.
What candidates do
Short, timeboxed scenarios that simulate engineering work: code review, debugging a production bug, programming and system design. You choose no AI, AI-first, or a mix
A real task from the job, such as a bug to fix or a campaign to plan
Which AI tool
Their own: “Bring-Your-Own LLM”. Their page names Copilot Agent Mode, Cursor and agentic IDEs as examples for AI-first scenarios
Their own: Claude Code, Codex, Claude Cowork or ChatGPT, on their own computer or in the browser
Who scores
People: “double-blind scoring by two certified engineers”. In AI-enabled scenarios, the work is compared with what a top model produces in one go, and scored on what the candidate adds
Lemonsignal gives a first read, against a scoring sheet written before anyone takes the task. Your team watches the session, checks the read and decides
Roles
Engineering: full-stack, frontend, backend, SRE and DevOps, engineering managers and data science
Engineering, product, design, marketing, data and finance
Watching for cheating
AI and plagiarism detection on every assessment, and human-powered async proctoring for no-AI scenarios
Checks the person doing the task is the person you sent it to, and that the work matches the conversation
What you get back
A strengths and weaknesses report for each candidate; candidates get technical feedback on their work, too
A recommendation, six AI skills and two or three job skills, each linked to the moment in the conversation it came from
Woven vs Lemonsignal: what the hiring team gets back
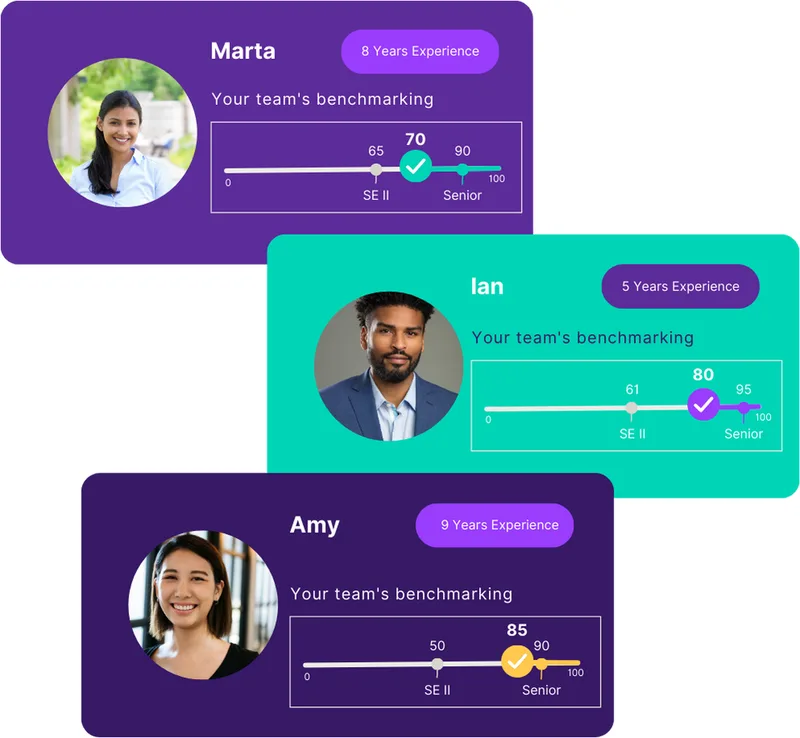
WovenWoven results: each candidate’s score placed against your team’s benchmarks by level. Image from woventeams.com, 28 Oct 2026.
Lemonsignal. A result for an engineer who fixed a real bug with Claude Code. Every score links to the moment in the conversation it came from.
LemonsignalDana Okafor
Dana OkaforBackend engineer · Task: Fix a double charge · Claude Code · 2 h 40 min
Checked by Lemonsignal
89%Strong match
Found the cause before letting the AI write a fix.
Tested the AI’s fix instead of trusting it.
Fixed the second service with what she built for the first.
UnderstandStrongHad it reproduce the double charge, and followed one payment through the code before any fix.Turn 2
BriefSolidGave it the logs and the files that matter, and said what it must not change.Turn 4
CheckStrongRan the tests on the AI’s first fix and turned it down. Proved her own fix with a test.Turns 12, 19
CorrectStrongTold it why the first fix was wrong and where to look instead.Turn 13
Sign offSolidA small change with its test, and a note on what she did not test.
ReuseStrongSaved the steps as a skill and used it to fix the refunds service.
Skills for the job
Finding the root causeAbove the bar
Proving a fix with a testAbove the bar
Code others can maintainAt the bar
What she handed in, as she handed it in. Each mark is a skill from her result.
UnderstandStrongSign offSolid
Change noteCharge once per order, even when the gateway retries
Cause: after a gateway timeout, the retry created a second charge.
Fix: each charge carries a key for its order, so a retry returns the first charge instead of making a new one.
Test: a retry after a timeout now charges once. All 48 tests pass.
Not tested: partial captures, which we do not use yet.
CheckStrongReuseStrong
payments/charge.pyThe fix
def create_charge(order, card):
- return gateway.charge(order.total, card)
+ key = f"order-{order.id}"
+ return gateway.charge(order.total, card,
+ idempotency_key=key)
tests/test_charge.pyFails before the fix, passes after
+def test_retry_charges_once(gw, order, card):
+ gw.fail_next_with(Timeout)
+ create_charge(order, card)
+ create_charge(order, card) # the retry
+ assert gw.charges_for(order) == 1
refunds/refund.pyThe same fix in the refunds service
def create_refund(charge, amount):
- return gateway.refund(charge.id, amount)
+ key = f"refund-{charge.id}"
+ return gateway.refund(charge.id, amount,
+ idempotency_key=key)
Should you choose Woven or Lemonsignal?
Choose Woven if
You hire only engineers and want two engineers to score every candidate.
You want short scenarios and a mix of AI-free and AI-first tasks.
You want candidates to get detailed technical feedback.
Choose Lemonsignal if
You hire outside engineering, too: product, design, marketing, data or finance.
You want the whole conversation with the AI recorded, as a session replay.
You want every score linked to the moment in the conversation it came from.
They are close: both let candidates use their own AI. Woven is for engineers, with short scenarios scored by two engineers. Lemonsignal covers roles beyond engineering, records the whole conversation with the AI, and links every score to its moment.
Does Lemonsignal let candidates bring their own AI tool, like Woven?
Yes: Claude Code, Codex, Claude Cowork or ChatGPT, on their own computer or in the browser.